What's new
5565 outputs · 169 models · 35 prompts · updated 2026-10-29
Analyses and comparisons →-
Particle 1 added
Particle-1’s temporary checks caught a 2048 merge bug, inspected a maze’s structure and tested Matrix Rain’s pause behavior.
Read update → OUTPUTparticle-1
 OUTPUTparticle-1
 OUTPUTparticle-1
-
GPT-6.1 Terra added
GPT-6.1 Terra paired browser checks with targeted game tests. Compare its movement and collision checks with GPT-6.1 Sol’s earlier debugging traces.
Read update → OUTPUTgpt-6.1-terra
 OUTPUTgpt-6.1-sol
 OUTPUTgpt-6.1-terra
 OUTPUTgpt-6.1-sol
-
What coding agents actually check
A coding agent says it has tested the app in a browser. You open it anyway, click the buttons, change the inputs, and check it yourself. You delegated verification, but still cannot tell which parts of the result you can rely on.
Read article → -
Kimi K3.1 Pro added
Kimi K3.1 Pro combined short browser-tool traces with scripted game checks, including a playable route through Platformer Dave.
Read update → OUTPUTkimi-k3.1-pro
 OUTPUTkimi-k3.1-pro
 OUTPUTkimi-k3.1-pro
 OUTPUTkimi-k3.1-pro
-
Mercury 3 added
Mercury 3 made game and UI state readable as text, then used that feedback to revise its builds.
Read update → OUTPUTmercury-3
 OUTPUTmercury-3
 OUTPUTmercury-3
-
MiniMax M3.1 Flash added
MiniMax revisited every build after editing, but repeated revisions sometimes consumed the full time budget.
Read update → OUTPUTminimax-m3.1-flash
 OUTPUTminimax-m3.1-flash
 OUTPUTminimax-m3.1-flash
-
Save runs, comparisons and models to My shortlist
Keep interesting builds and models close at hand, return to them later, and open your saved models side by side. No account needed.
Read update → -
Nemotron 3.5 Super VL and Muse Spark Open added
Nemotron’s cube shows a concrete repair sequence; Muse Spark Open’s saved runs contain fewer browser checks.
Read update →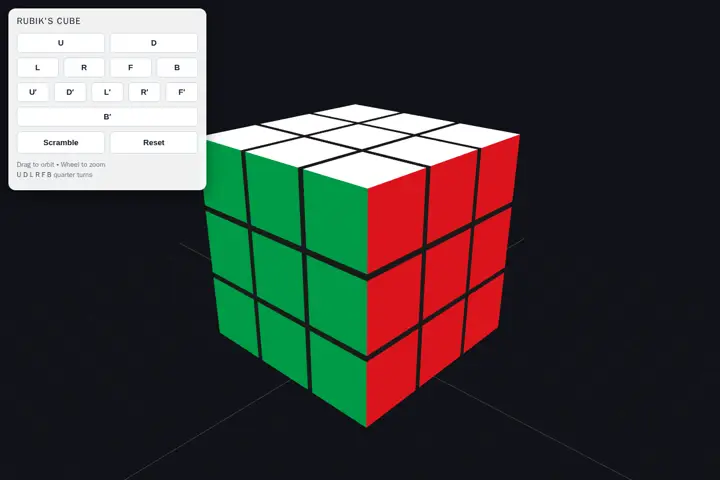 OUTPUTnemotron-3.5-super-vl
 OUTPUTmuse-spark-open
 OUTPUTnemotron-3.5-super-vl
-
Five Qwen models refreshed
173 successful model/prompt builds published in autonomous sessions with browser tools. See each run for its output, transcript, runtime and cost.
Read update → OUTPUT · TIMED OUTqwen3-vl-30b-a3b-instruct
 OUTPUTqwen-2.5-72b-instruct
 OUTPUTqwen3.5-35b-a3b
 OUTPUTqwen3-coder-next
-
Gemini 4 Argon: 3 more builds
3 successful model/prompt builds published in autonomous sessions with browser tools. See each run for its output, transcript, runtime and cost.
Read update → OUTPUTgemini-4-argon
 OUTPUTgemini-4-argon
 OUTPUTgemini-4-argon
-
Muse Wonder, Ling 3.1 Flash, LFM 2.5 and Gemini 4 Argon added
Ling repeatedly revised after browser checks; Muse Wonder exercised controls across every prompt.
Read update → OUTPUTling-3.1-flash
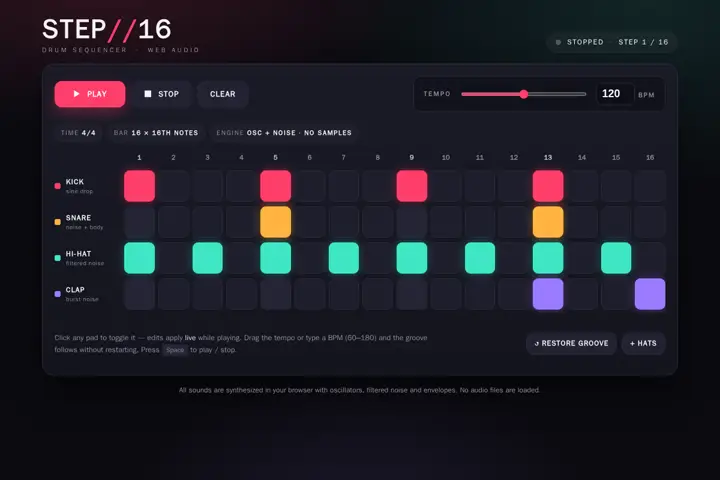 OUTPUTmuse-wonder
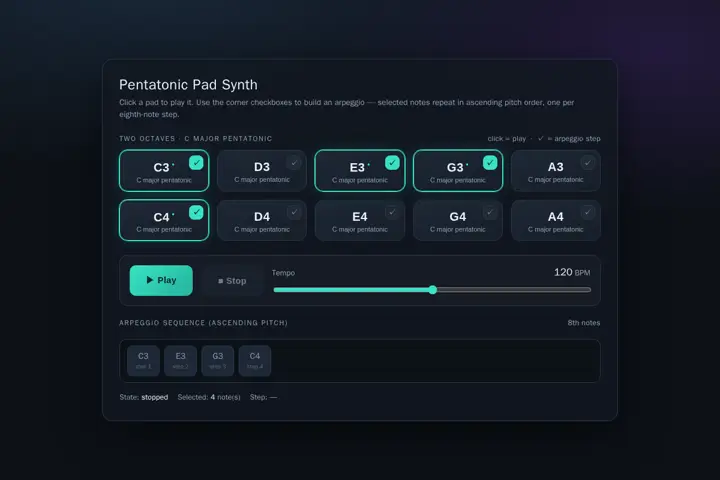 OUTPUTling-3.1-flash
-
Grok 4.7, Qwen3.8 Max and Gemma builds completed
52 successful model/prompt builds published in autonomous sessions with browser tools. See each run for its output, transcript, runtime and cost.
Read update → OUTPUTmimo-v2.6-flash
 OUTPUTgemma-4-26b-a4b-it
 OUTPUTminimax-m3
 OUTPUTgemma-4-26b-a4b-it
-
496 saved builds published across 18 models
We have published 496 successful browser-agent builds across 18 models. These outputs were generated in earlier runs and saved in Cloudflare; this release brings them into the gallery without rerunning the models.
Read update → OUTPUTgpt-oss-120b
 OUTPUTqwen3-8b
 OUTPUTnemotron-3-nano-30b-a3b
 OUTPUT · TIMED OUTlaguna-s-2.1
-
Haiku, Qwen, GPT-5 Mini and MiniMax refreshed
174 successful model/prompt builds published in autonomous sessions with browser tools. See each run for its output, transcript, runtime and cost.
Read update → OUTPUTclaude-haiku-5.5
 OUTPUTqwen3.8-flash
 OUTPUTqwen3.6-35b-a3b
 OUTPUTgpt-5-mini
-
Step 5, Qwen3.8 27B, Gemini 3.5 Flash Lite and MiMo Pro refreshed
139 successful model/prompt builds published in autonomous sessions with browser tools. See each run for its output, transcript, runtime and cost.
Read update → OUTPUTqwen3.8-27b
 OUTPUTmimo-v2.6-pro
 OUTPUTgemini-3.5-flash-lite
 OUTPUTstep-5-preview
-
GPT-5 Nano, GPT-6 Luna, GLM-5.3 Flash, MiMo and Gemma refreshed
139 successful model/prompt builds published in autonomous sessions with browser tools. See each run for its output, transcript, runtime and cost.
Read update → OUTPUTgpt-5-nano
 OUTPUTgpt-6-luna
 OUTPUTglm-5.3-flash
 OUTPUTgpt-5-nano
-
Terra, Gemini Pro, Grok, Qwen Max and Kimi refreshed
140 successful model/prompt builds published in autonomous sessions with browser tools. See each run for its output, transcript, runtime and cost.
Read update → OUTPUTgpt-5.6-terra
 OUTPUTgemini-3.1-pro-preview
 OUTPUTgrok-4.7
 OUTPUTqwen3.8-max-0902
-
Refreshed DeepSeek V4.1 Flash
DeepSeek V4.1 Flash has 34 complete outputs in this refresh across the current 35 prompts, with HTML, previews, transcripts and OpenRouter-reported usage available on each run page.
Read update → OUTPUTdeepseek-v4.1-flash
 OUTPUTdeepseek-v4.1-flash
 OUTPUTdeepseek-v4.1-flash
 OUTPUTdeepseek-v4.1-flash
-
Gemini 3.8 Flash and Muse Spark 1.3
Gemini 3.8 Flash and Muse Spark 1.3 are now available across the current 35 prompts. This batch produced 69 complete outputs: 34 from Gemini and all 35 from Muse, with HTML, previews, transcripts and OpenRouter-reported usage on each run page.
Read update → OUTPUTgemini-3.8-flash
 OUTPUTmuse-spark-1.3
 OUTPUTgemini-3.8-flash
 OUTPUTmuse-spark-1.3
-
Ten models refreshed with 322 complete outputs
This refresh publishes 322 complete results across ten models, each with HTML, previews, a transcript and OpenRouter-reported usage. The models ran the current 35 prompts with the pi harness and browser tools available.
Read update → OUTPUT · STOPPED BY AN API ERRORgemma-4-26b-a4b-it
 OUTPUTqwen-2.5-7b-instruct
 OUTPUTnova-lite-v1
 OUTPUTqwen3.5-flash-02-23
-
Ten models refreshed with 340 complete outputs
This refresh publishes 340 complete results across ten models, each with HTML, previews, a transcript and OpenRouter-reported usage. The models ran the current 35 prompts with the pi harness and browser tools available.
Read update → OUTPUTministral-14b-2512
 OUTPUTstep-3.5-flash
 OUTPUTgemma-4-31b-it
 OUTPUT · STOPPED BY AN API ERRORqwen3-235b-a22b-2507
-
Five models refreshed with the browser harness
Fresh runs of 35 prompts are now published for five models:
Read update → OUTPUTmistral-nemo
 OUTPUTling-3.0-flash
 OUTPUTgpt-oss-20b
 OUTPUTllama-3.1-8b-instruct
-
Added Mistral Large 4
Mistral Large 4 joins the gallery with runnable outputs for all 35 current prompts.
Read update → OUTPUT · STOPPED BY AN API ERRORmistral-large-4-0
 OUTPUT · STOPPED BY AN API ERRORmistral-large-4-0
 OUTPUT · STOPPED BY AN API ERRORmistral-large-4-0
 OUTPUT · STOPPED BY AN API ERRORmistral-large-4-0
-
Refreshed DeepSeek V4.1 Flash
A fresh run on our rewritten prompts: 33 complete builds with browser iteration and new previews.
Read update → OUTPUTdeepseek-v4.1-flash OUTPUTdeepseek-v4.1-flash
 OUTPUTdeepseek-v4.1-flash
 OUTPUTdeepseek-v4.1-flash
-
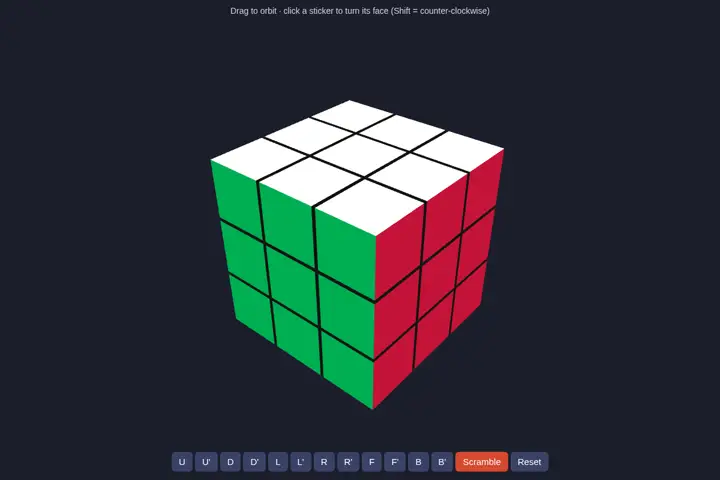
Added Claude Sonnet 5.5
Claude Sonnet 5.5 produced HTML for all 35 prompts, checking its work in the browser on every run.
Read update → OUTPUTclaude-sonnet-5.5
 OUTPUTclaude-sonnet-5.5
 OUTPUTclaude-sonnet-5.5
 OUTPUTclaude-sonnet-5.5
-
Added GPT-6.1 Sol
GPT-6.1 Sol produced HTML for all 35 prompts, using browser inspection and iteration in our new pipeline.
Read update → OUTPUTgpt-6.1-sol
 OUTPUTgpt-6.1-sol
 OUTPUTgpt-6.1-sol
 OUTPUTgpt-6.1-sol
-
Qwen3.8: the 27B meets the 2.4T flagship
We added the smaller Qwen3.8-27B, so we put it straight up against the 2.4-trillion-parameter Qwen3.8-2.4T-A95B already in the gallery — same family, roughly two orders of magnitude apart in size. Both are reliable builders (34 of 35 and 35 of 35 shipped), so the story is entirely in the quality.
Read update → OUTPUT · TIMED OUTqwen3.8-27b
 OUTPUTqwen3.8-2.4t-a95b
 OUTPUTqwen3.8-27b
 OUTPUTqwen3.8-2.4t-a95b
-
Added Grok 4.6
xAI's Grok 4.6 ran the full matrix clean — 35 of 35 builds shipped — with a clear strength in generative canvas work.
Read update → OUTPUTgrok-4.6
 OUTPUTgrok-4.6
 OUTPUTgrok-4.6
 OUTPUTgrok-4.6
-
Meta Muse: Spark 1.2 vs Glimmer 30B
Meta shipped two new Muse models, so we ran both through the same 35 one-shot prompts. Neither failed to ship a single build — 35 of 35 runnable each — so the gap between them is entirely about quality, not reliability.
Read update → OUTPUTmuse-spark-1.2
 OUTPUTmuse-glimmer-30b
 OUTPUTmuse-spark-1.2
 OUTPUTmuse-glimmer-30b
-
Added Qwen3.8-2.4T-A95B
Alibaba's 2.4-trillion-parameter Qwen3.8-2.4T-A95B turned in the most consistent run of the batch — 35 of 35 builds shipped, zero blank or crashed, and the tightest quality spread in the set.
Read update → OUTPUTqwen3.8-2.4t-a95b
 OUTPUTqwen3.8-2.4t-a95b
 OUTPUTqwen3.8-2.4t-a95b OUTPUTqwen3.8-2.4t-a95b
-
ByteDance Seed: 2.0 Code vs 2.1 Turbo
Two new ByteDance Seed models went through the matrix together — both 35 of 35 on build reliability, but with opposite temperaments.
Read update → OUTPUTseed-2.0-code
 OUTPUTseed-2-1-turbo
 OUTPUTseed-2.0-code
 OUTPUTseed-2-1-turbo
-
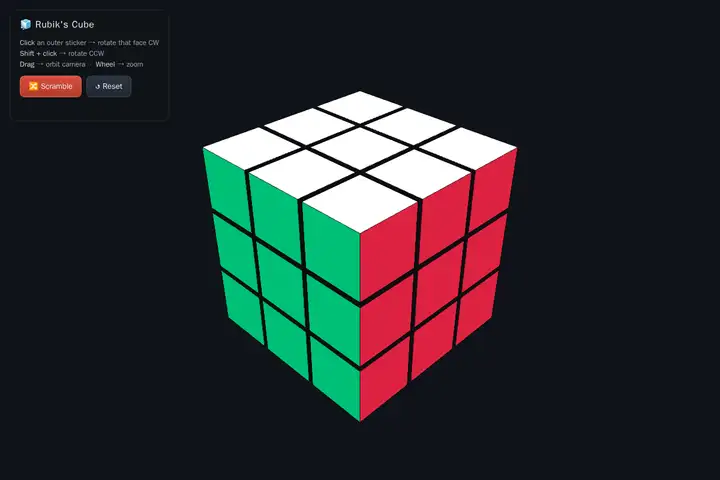
Added Qwen3.8-Max
Alibaba's new flagship Qwen3.8-Max ran all 35 one-shot prompts with zero build failures — a clean sweep of the matrix, and a solid mid-pack showing on quality.
Read update →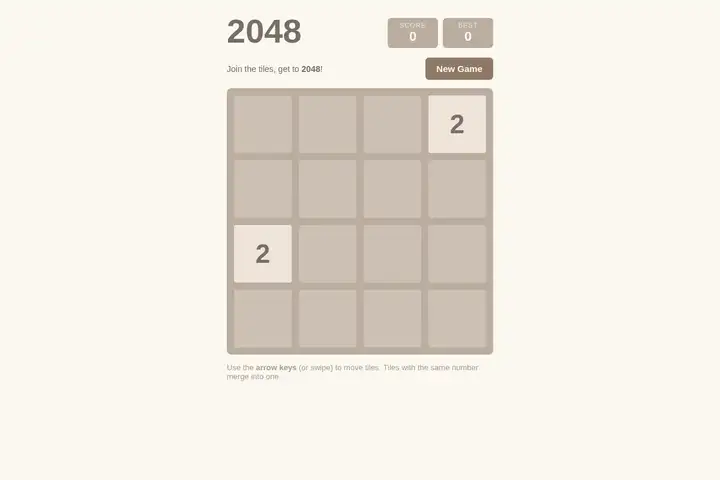 OUTPUTqwen3.8-max
 OUTPUTqwen3.8-max
 OUTPUTqwen3.8-max
 OUTPUTqwen3.8-max
-
Compare any models across every prompt
A new side-by-side grid: pick up to 10 models and see how each one built every prompt, in one scrollable table.
Read update → -
Kimi K3 vs Claude Opus 4.8, one shot each
We ran Moonshot's new Kimi K3 and Claude Opus 4.8 through the same 34 one-shot prompts, same harness, and they finish within a hair of each other — K3 at 3.24 average, Opus at 3.12. The interesting part is where each one misses.
Read update → OUTPUTkimi-k3
 OUTPUTclaude-opus-4.8
 OUTPUTkimi-k3
 OUTPUTclaude-opus-4.8
-
Added Moonshot Kimi K3
Moonshot shipped Kimi K3, a million-token model, so we added it to the matrix and ran all 34 one-shot prompts against it — same harness, same single-shot rules as every other build in the gallery.
Read update → OUTPUTkimi-k3 OUTPUTkimi-k3
 OUTPUTkimi-k3
 OUTPUTkimi-k3
-
Added GLM-5.2, MiMo v2.5 and 3 more models
Five more models joined the matrix this week, and we re-ran every prompt against them. The alien-shooter build is a good stress test: it needs a game loop, collision, and input handling all in one file, so the gap between models shows up fast.
Read update → OUTPUTdeepseek-v4-pro
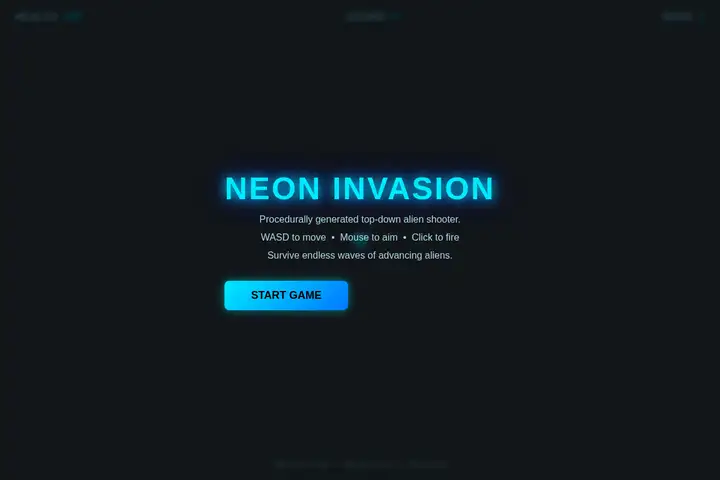 OUTPUTkimi-k2.7-code
 OUTPUTglm-5.2
 OUTPUTminimax-m2.7
-
Two-tier artifact evaluation is live
Every build now carries a two-tier grade. Tier 1 measures the artifact deterministically — how much of the screen moves, whether it responds to input, console and JS errors — and Tier 2 hands those measurements plus a capture to a vision model for the final verdict.
Read update → OUTPUTclaude-opus-4.8
 OUTPUTdeepseek-v4-pro OUTPUTclaude-opus-4.8
 OUTPUTdeepseek-v4-flash
-
New prompt: Fluid simulation
A real-time WebGL fluid sim in one file — the hardest prompt in the set so far.
Read update → OUTPUTdeepseek-v4-pro
 OUTPUTglm-5
 OUTPUTminimax-m2.7 OUTPUTclaude-opus-4.8